Pods and Nodes Failure Use Case
Routine Pod and Node Failures Shouldn’t Stop Your Operations.
Greymatter instantly detects failing pods and nodes. It then automatically redirects traffic to healthy instances so your mission-critical operations continue without interruption.

When a Minor Glitch Turns into a Major Problem
The Real Cost of Failed Pods and Nodes
In traditional systems, a failed pod or node silently accepts requests but never responds. This creates black holes in your infrastructure. Screens freeze, data stops flowing, and teams lose visibility exactly when they need it most.

Your live data becomes unreliable.
Failed components freeze your operational picture mid-task. Teams can no longer trust their dashboards or proceed with confidence during critical moments.

Your teams get stuck playing catch-up.
Instead of focusing on the mission, engineers drop everything to hunt down problems. This reactive firefighting leads to burnout, delays, and unnecessary costs.

Operations come to a standstill.
A minor infrastructure glitch escalates into a major distraction. In high-stakes environments, even brief delays can mean losing track of critical objectives.
See the Operational Story
How Greymatter Makes Pod and Node Failures Invisible
Watch how we ensure that your mission doesn’t stop when systems fail.
This short video demonstrates what happens during a pod or node failure in a real scenario. You’ll see systems freeze while Greymatter detects the issue instantly, reroutes traffic seamlessly to healthy services, and keeps everything running smoothly.
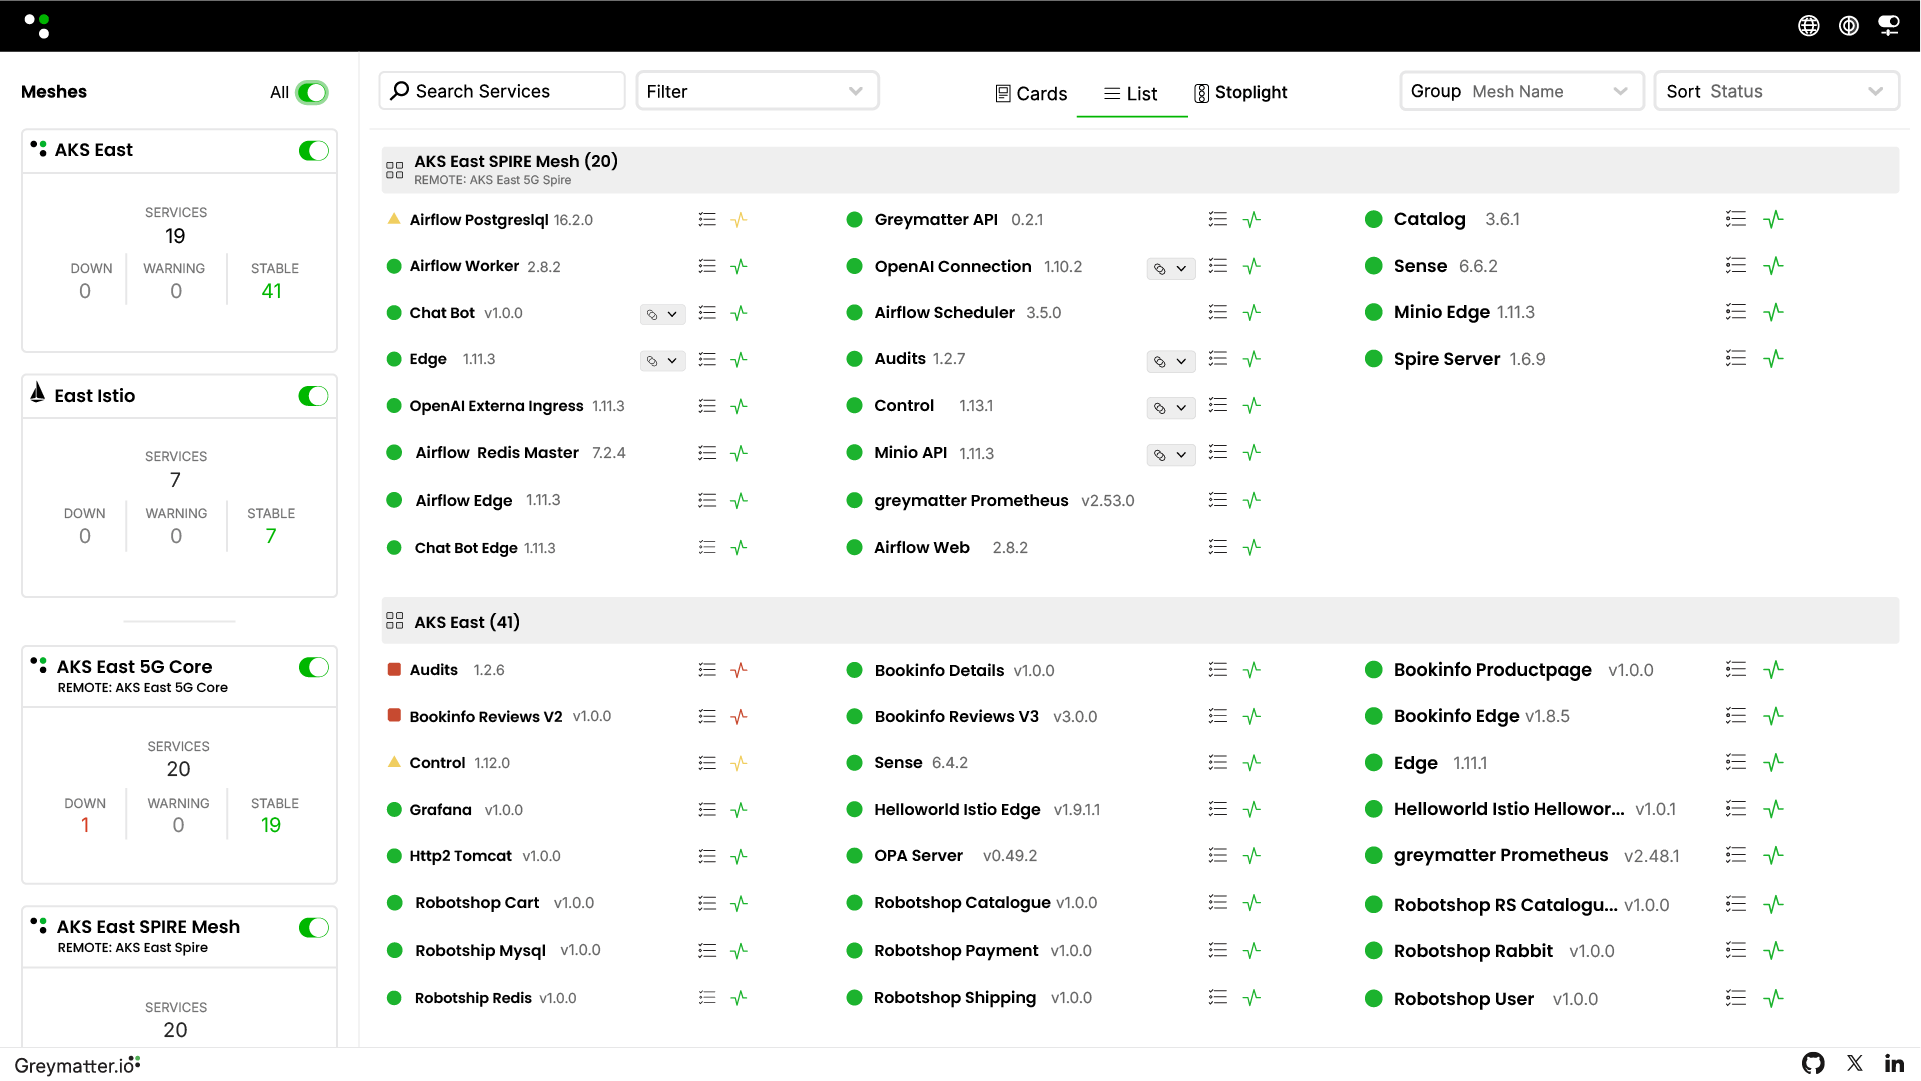
Greymatter is your automated traffic controller. It continuously monitors application, API, and AI Agent health. It spots failures the moment they occur and reroutes users to healthy workloads with zero disruption. Your teams get instant visibility into application health and security. No guesswork and no manual intervention.
See the Proof
Watch Failure Get Detected, Contained, and Routed Around
This in-depth technical demo shows what happens before, during, and after a pod or node failure in a live environment.
You will see a healthy baseline, a failure introduced in real time, the affected instance marked unhealthy, and traffic removed from that failed destination automatically. From there, you will see how Greymatter supports failover across a broader federated environment, enforces declared policy from Git, and gives teams the visibility to verify what happened during and after the event.
This is not just failure detection. It is visible proof that the environment can absorb failure without forcing teams into manual recovery mode.